What Is Data Annotation for AI? A Guide to Labeled Training Data
What data annotation for AI is
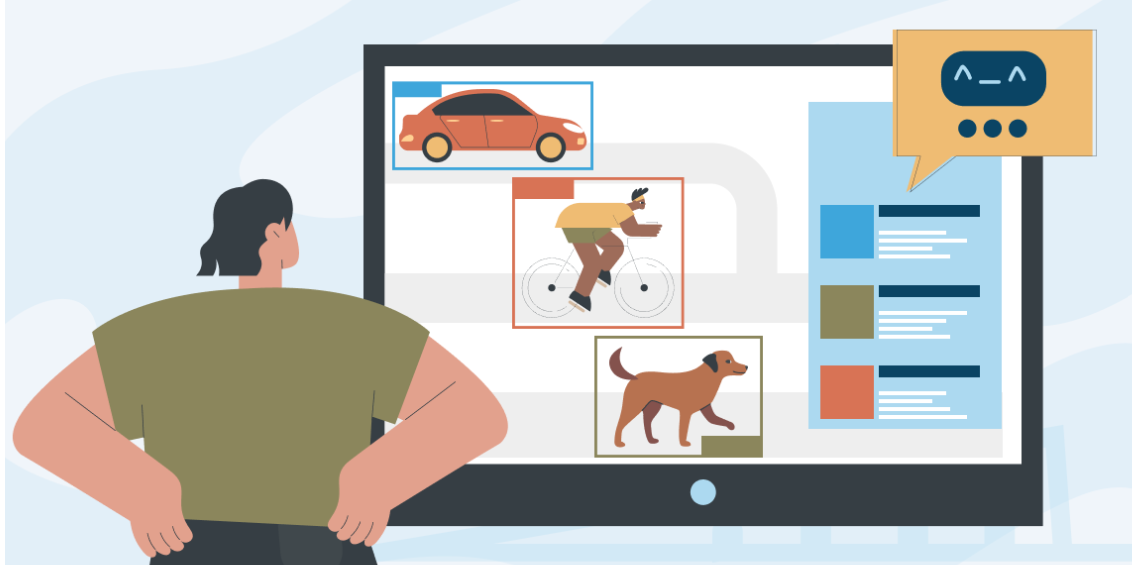
AI data annotation is the process of labeling and organizing raw data so artificial intelligence (AI) systems can recognize patterns, interpret information, and make accurate predictions. It involves adding meaningful tags, categories, or contextual details to datasets used to train machine learning models. For example, annotators may label images of cats and dogs, identify names and locations in text, transcribe spoken language from audio recordings, or mark objects and actions in video footage. These labeled examples help algorithms understand what different data points represent and how to process similar information in the future.
Data annotation for AI is a fundamental step in developing reliable machine learning models, particularly those trained through supervised learning. The quality of annotated training data directly influences how effectively a model learns, generalizes to new inputs, and performs in real-world applications. Depending on the project, the annotation process may involve human experts, automated tools, or a combination of both to improve efficiency and maintain accuracy.
Why AI needs labeled training data
Labeled training data provides AI systems with clear examples of what they need to recognize, classify, or predict. During supervised learning, algorithms analyze input data alongside its corresponding labels to identify patterns and relationships that can be applied to new, unseen information. For example, an AI model trained on emails labeled as “spam” or “not spam” learns to distinguish unwanted messages from legitimate communication. This is why data labeling is essential for effective AI model training data: without accurate labels, a model may struggle to learn the right patterns and produce reliable predictions. Although some machine learning approaches can learn from unlabeled data, labeled examples remain fundamental to many AI applications, including image recognition, sentiment analysis, and speech processing.
The quality of data annotation in machine learning directly affects model accuracy, consistency, and ability to generalize to real-world scenarios. Incorrect, inconsistent, or biased labels can teach algorithms misleading patterns, resulting in unreliable outputs and additional training costs. A structured data labeling process helps reduce these risks by establishing clear annotation guidelines, applying consistent labeling criteria, and reviewing completed datasets for accuracy. In practice, data labeling in machine learning also enables teams to evaluate model performance against known answers and identify areas for improvement.
What the main types of data annotation are
The main types of data annotation vary depending on the data format and the task an AI model needs to perform, from understanding human language to recognizing objects and interpreting audio or video.
| Data type | Annotation examples | Common application |
| Text | Sentiment labels, named entities, intent tags, text classification | NLP, chatbots, sentiment analysis, search engines |
| Image | Bounding boxes, image classification, segmentation, keypoints | Computer vision, object detection, facial recognition |
| Audio | Transcription, speaker identification, sound event labels | Speech recognition, voice assistants, audio analysis |
| Video | Object tracking, action labels, frame-by-frame annotation | Autonomous driving, surveillance, activity recognition |
| 3D | 3D bounding boxes, point cloud segmentation, object tracking | Robotics, autonomous vehicles, 3D scene understanding |
| Geospatial | Geographic coordinates, map feature labeling, road and building outlines, land-use classification | GIS, satellite imagery analysis, navigation systems, urban planning |
Text annotation
Text annotation involves labeling written data to help machine learning models understand language, meaning, and context. Common tasks include sentiment analysis, named entity recognition, text classification, and intent detection, which support chatbots, search engines, and natural language processing (NLP) applications.
Image annotation
Image annotation adds labels and visual markers to images so AI models can identify objects, people, and other elements. Techniques include bounding boxes, polygon annotation, and image segmentation, which are widely used in medical imaging, facial recognition, and autonomous driving.
Audio and speech annotation
Audio and speech data annotation involves transcribing speech, identifying speakers, labeling sounds, and adding timestamps to recordings. It helps AI systems recognize spoken language, interpret voice commands, analyze conversations, and distinguish speech from background noise.
Video annotation
Video annotation labels objects, actions, and events across video frames, often tracking how they move over time. It is essential for video surveillance, traffic monitoring, activity recognition, and autonomous vehicle systems.
3D point cloud annotation
This type of annotation labels three-dimensional data collected by sensors such as LiDAR. Annotators identify and classify objects in 3D space, helping autonomous vehicles and robotics systems understand their surroundings and estimate object positions.
Geospatial data annotation
Geospatial annotation adds labels to location-based data, including satellite imagery, maps, and geographic coordinates. It supports applications such as urban planning, agricultural monitoring, environmental analysis, and navigation.
Data annotation vs. data labeling: What's the difference
Data annotation and data labeling are closely related terms in artificial intelligence, and they are often used interchangeably. However, the main difference lies in the scope of the work. Data labeling typically involves assigning predefined categories or tags to raw data, such as marking an email as spam or identifying an image as a car. Data annotation for AI can cover a broader range of tasks, including drawing bounding boxes around objects, highlighting specific words in text, adding timestamps to audio recordings, or identifying relationships between entities. Both approaches transform raw information into structured datasets that machine learning algorithms can use to learn patterns and make predictions.
In practice, data labeling for AI is often considered a subset of data annotation, although the exact terminology varies between projects and providers. For simple classification tasks, assigning a label may be sufficient to create useful labeled training data. More complex AI applications, such as autonomous driving, natural language processing, and video analysis, may require detailed annotations that capture an object's location, context, or relationship to other data points. Understanding this distinction helps businesses define project requirements, select appropriate annotation tools, and establish quality standards.
How the AI data annotation process works
The AI data annotation process begins with defining the machine learning model’s goals and identifying the type of data required for training. Teams collect relevant raw data, including text, images, audio recordings, and video, then clean and organize it by removing duplicates, irrelevant entries, and corrupted files. Next, they establish clear annotation guidelines that specify which labels to apply and how to handle ambiguous examples. During the labeling stage, human annotators, AI-powered tools, or a combination of both add meaningful tags, categories, transcripts, or object markers to the dataset.
A structured data annotation workflow also includes quality assurance to ensure labels are accurate, consistent, and aligned with project requirements. Reviewers may inspect samples, compare annotations from multiple workers, and correct errors before approving the dataset. Once validated, the labeled data is organized into training, validation, and test sets, depending on the model development process. The model can then learn from annotated examples, and its performance can reveal gaps that require additional labeling or revised guidelines. This iterative data annotation process helps improve training data quality, reduce labeling errors, and support more reliable machine learning outcomes. Combining human expertise with automation can also increase efficiency while maintaining the level of accuracy needed for a specific AI application.
What the main data annotation techniques are
The main data annotation techniques depend on the data type, the AI model’s objectives, and the patterns it needs to learn. Text annotation for AI involves classifying documents, identifying keywords, and tagging entities such as people, organizations, and locations. Image annotation uses methods such as bounding boxes, polygons, and segmentation masks to identify objects and define their boundaries. Video annotation extends these techniques across consecutive frames, allowing algorithms to track moving objects and recognize activities. Audio annotation includes speech transcription, speaker identification, and sound classification, helping machine learning models interpret spoken language and other audio signals.
NLP data annotation focuses on preparing text and language data for natural language processing models. Common techniques include named entity recognition (NER), which identifies names, dates, and locations; sentiment analysis, which categorizes opinions as positive, negative, or neutral; and intent classification, which determines what a user wants to achieve with a message. Part-of-speech tagging identifies grammatical roles, while relationship extraction reveals connections between entities in a text. For generative AI applications, annotation can also involve ranking model-generated responses, evaluating answer relevance, and identifying inaccurate or harmful content. Choosing the right data annotation techniques requires clear labeling guidelines, consistent criteria, and quality checks to reduce errors.
How to ensure data annotation quality
Ensuring high-quality machine learning data annotation starts with clear labeling guidelines that define categories, provide examples, and explain how to handle ambiguous cases. Consistent instructions help annotators apply the same criteria across text, images, audio, and video datasets, reducing discrepancies that could affect model performance. Selecting qualified annotators and providing task-specific training are equally important, especially for specialized domains that require subject-matter expertise. Teams should also use appropriate annotation tools to standardize the workflow, flag uncertain examples, and minimize manual errors. Before large-scale labeling begins, pilot projects can help identify unclear instructions and refine the annotation process. These steps establish a reliable foundation for producing accurate, consistent, and relevant training datasets.
A robust quality assurance process combines automated checks with human review to verify the accuracy and consistency of training data labeling. Teams can measure inter-annotator agreement to identify disagreements, audit random samples, and use expert reviewers to resolve complex cases. Automated validation rules can detect missing labels, invalid formats, and duplicate records, while regular feedback helps annotators correct recurring mistakes. Documenting annotation decisions and tracking revisions makes quality issues easier to investigate and resolve. By continuously evaluating and improving annotation standards, organizations can reduce rework, control labeling costs, and provide machine learning models with dependable data for training and evaluation.
What challenges can affect data annotation projects
Data annotation projects can face several challenges that affect dataset quality, project timelines, and AI model performance. One of the most common issues is inconsistent labeling, as different annotators may interpret instructions differently, especially when working with complex or ambiguous data. Large-scale projects can also be costly and time-consuming, requiring skilled workers, specialized tools, and ongoing quality checks. AI data annotation services help organizations overcome these challenges by providing trained annotators, established quality control processes, and scalable solutions tailored to specific project requirements. For example, natural language processing annotation can be particularly challenging when text contains sarcasm, cultural references, ambiguous expressions, or language-specific nuances that automated tools may struggle to interpret correctly. Other obstacles include biased or unrepresentative datasets, limited availability of domain experts, data privacy concerns, and difficulties maintaining consistent standards across multiple languages and data types. Automated annotation tools can accelerate the process but may introduce errors that require human review. To overcome these challenges, organizations should establish clear annotation guidelines, train annotators, implement quality assurance procedures, and regularly audit labeled datasets. Combining human expertise with automation helps improve annotation consistency, manage costs, and produce reliable training data for machine learning models.
Recommended content
Localizing Voice-Overs for Corporate Training: How to Choose the Right Accent and Tone
Cultural Adaptation of Legal Disclaimers and Privacy Policies for International Sites
B2B vs. B2C Localization: How Target Audiences Change Your Translation Strategy